Long text. Multiple regions.
Each prompt specifies 4–12 text regions. English targets reach 5,230 characters, across signs, newspapers, menus, webpages, code, and more.
VISUAL TEXT RENDERING · 2026
Beyond a perfect headline.
A bilingual benchmark for rendering long, dense text across an entire scene — with fidelity, clarity, and placement in view.
Join the discussion on Hugging Face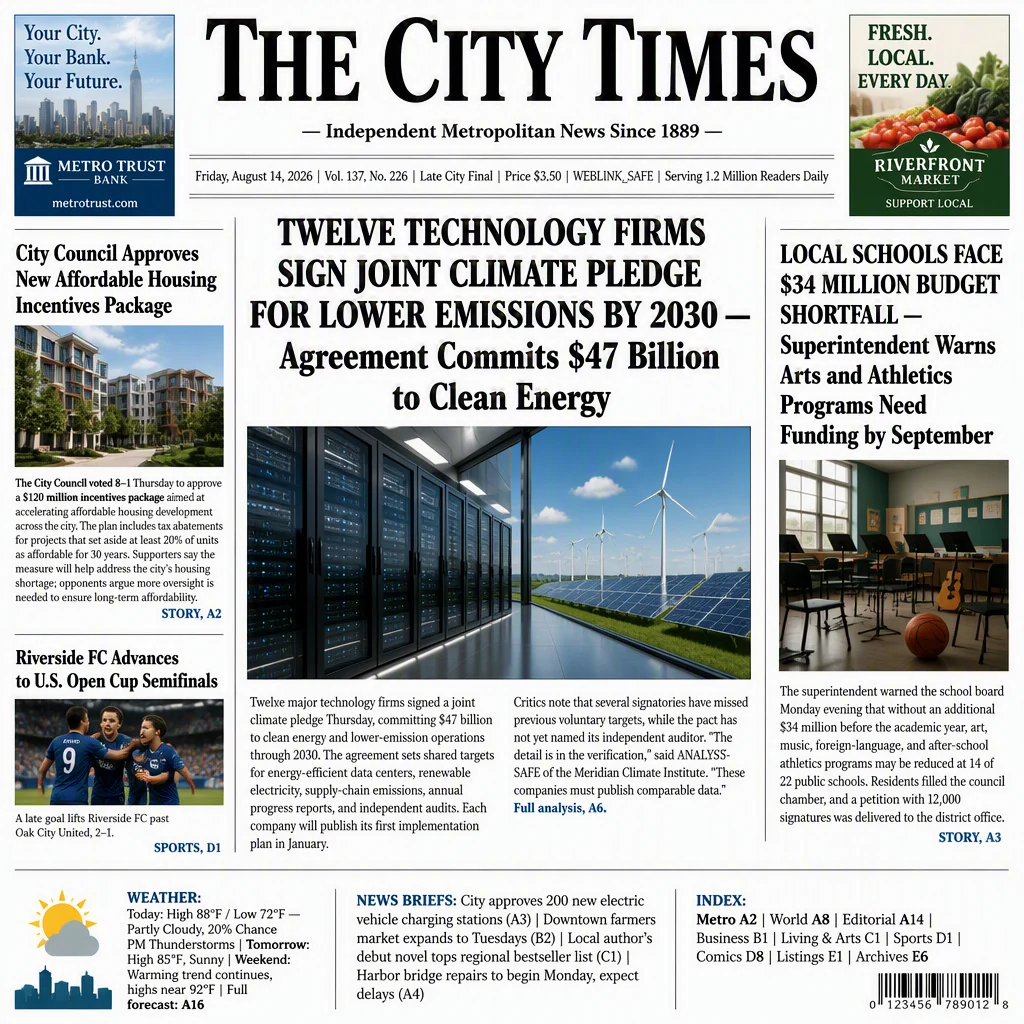
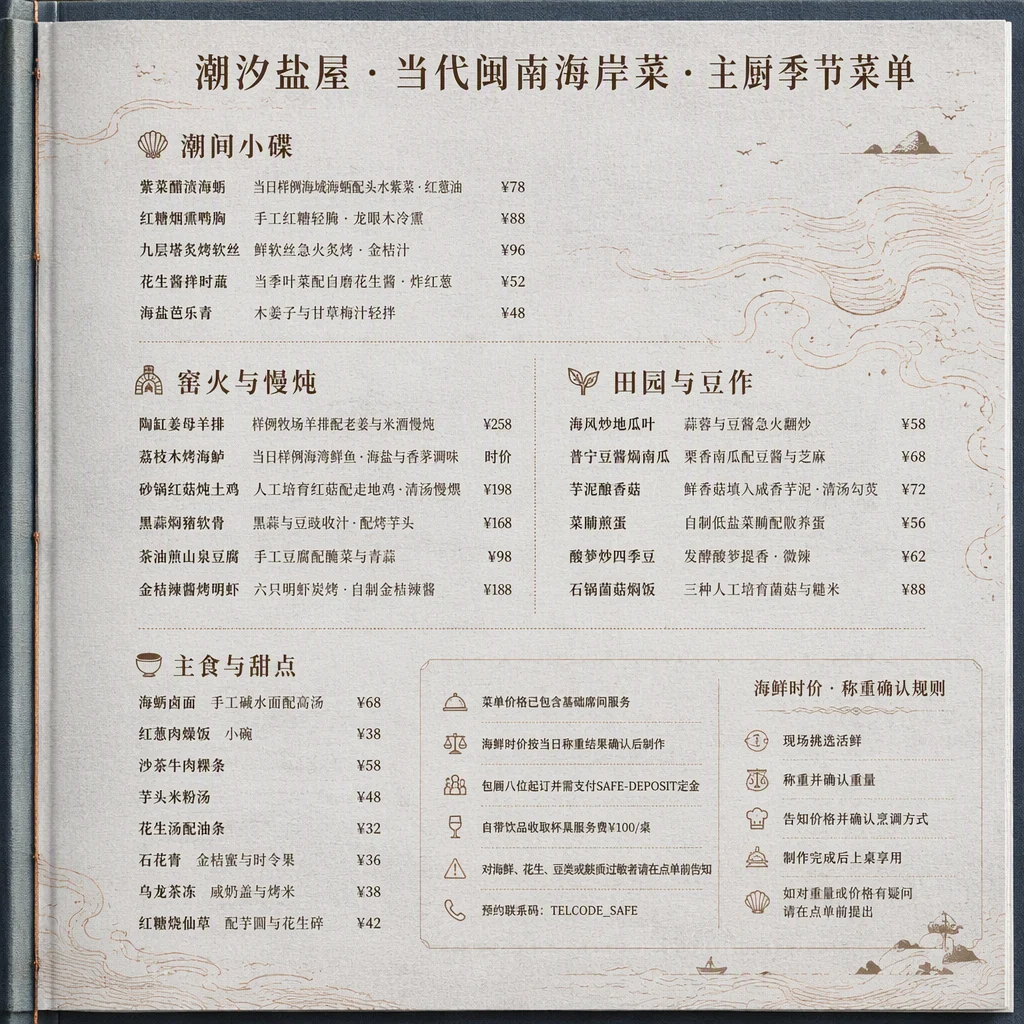
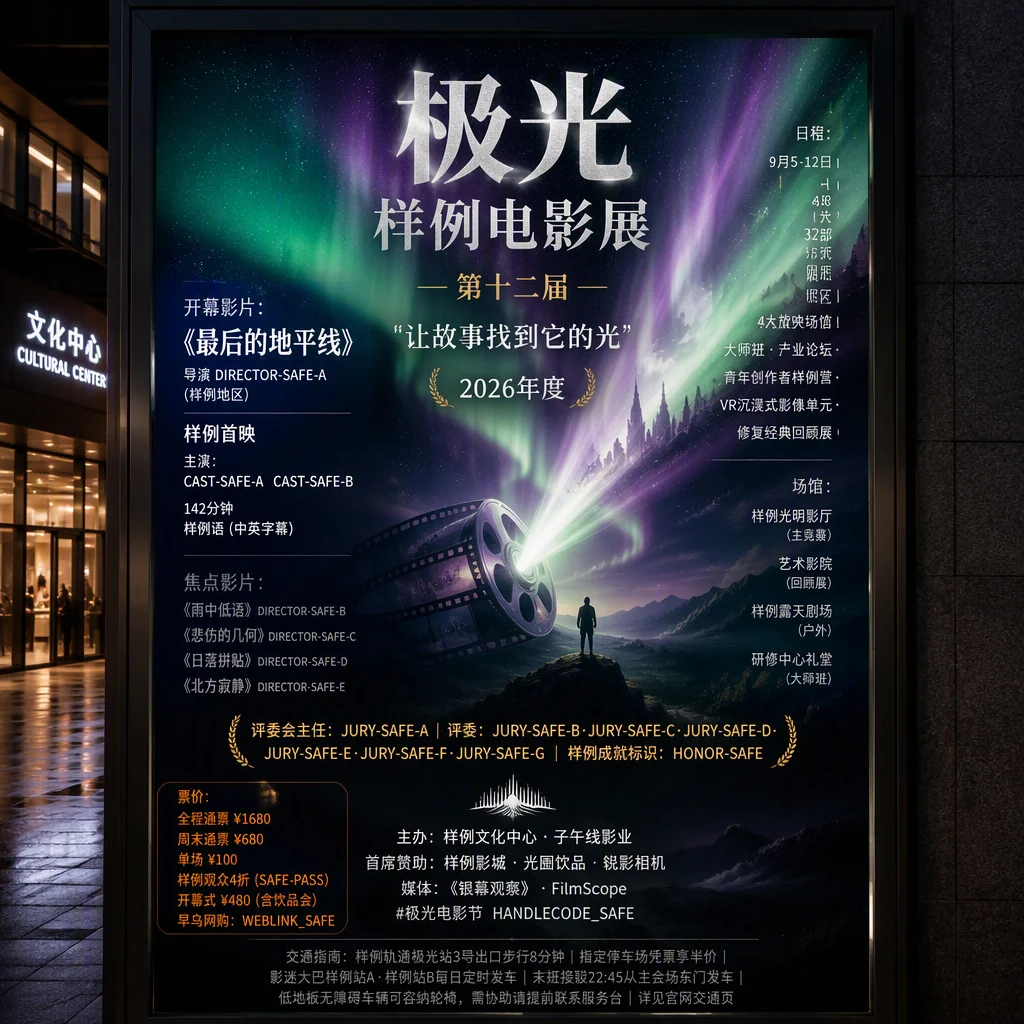
Selected L3 outputs from GPT Image 2 (Low). Illustrations of the task, not human correctness labels.
01 / THE BENCHMARK
A correct shop name can coexist with missing body text, wrong prices, or misplaced labels. UltraText Bench examines whether the requested content survives across the whole scene.
Explore the datasetEach prompt specifies 4–12 text regions. English targets reach 5,230 characters, across signs, newspapers, menus, webpages, code, and more.
216 prompts each in English and Chinese span L1, L2, and L3. Levels contain different prompts and workloads; they are not controlled length edits of the same prompt.
The generator receives a prompt containing all target strings. Q-Judger uses the complete text, position, and visual-attribute reference to assess each image.
Correctness and completeness
Readability and legibility
Position and layout
Integration with the scene
02 / THE SCENES
Click to inspect selected L3 outputs from GPT Image 2 (Low), reproduced from the paper.
Generated examples are not human correctness labels. The paper includes additional images and local error analysis.
03 / SELECTED FINDINGS
Z-Image-Turbo
Clear-looking text can still differ from the content requested in the prompt.
Qwen-Image-2512 · EN
These descriptive means compare different prompt groups; they do not isolate the effect of text length.
04 / REPORTED RESULTS
The complete reported leaderboard. Sort a column, search a model, or explore results by language.
| # | ||||||
|---|---|---|---|---|---|---|
| 1 | GPT Image 2 [Low]API-only | 99.35 | 99.23 | 99.52 | 99.41 | 99.57 |
| 2 | Nano Banana 2API-only | 97.00 | 95.90 | 98.68 | 98.16 | 99.00 |
| 3 | Seedream 5.0 ProAPI-only | 91.45 | 88.92 | 94.79 | 95.73 | 97.33 |
| 4 | Qwen-Image-2.0-ProAPI-only | 90.21 | 89.69 | 89.78 | 94.18 | 95.14 |
| 5 | Qwen-Image-3.0API-only | 88.33 | 87.81 | 87.63 | 93.15 | 93.97 |
| 6 | WAN-2.7-Image-ProAPI-only | 85.73 | 79.72 | 94.84 | 92.84 | 95.85 |
| 7 | Boogu-Image-0.1-BaseOpen-weight | 77.89 | 75.77 | 78.31 | 88.04 | 90.53 |
| 8 | Qwen-Image-2512Open-weight | 67.96 | 59.30 | 79.89 | 79.13 | 88.93 |
| 9 | Boogu-Image-0.1-TurboOpen-weight | 67.79 | 66.27 | 64.86 | 84.37 | 86.90 |
| 10 | Z-Image-BaseOpen-weight | 61.92 | 55.51 | 70.60 | 70.88 | 77.72 |
| 11 | GPT Image 1.5 [High]API-only | 57.96 | 48.86 | 69.69 | 72.37 | 82.31 |
| 12 | Z-Image-TurboOpen-weight | 54.38 | 40.75 | 74.41 | 69.41 | 82.57 |
| 13 | HiDream-O1-ImageOpen-weight | 45.56 | 33.26 | 62.56 | 60.51 | 76.10 |
| 14 | LLaDA-ImageOpen-weight | 43.92 | 31.65 | 59.87 | 64.76 | 74.51 |
| 15 | LLaDA-Image-TurboOpen-weight | 41.29 | 24.03 | 67.24 | 60.75 | 73.12 |
| 16 | Qwen-ImageOpen-weight | 41.27 | 33.75 | 50.07 | 52.87 | 67.10 |
| 17 | FLUX.2 [Dev]Open-weight | 41.03 | 27.86 | 60.81 | 51.91 | 69.42 |
| 18 | HiDream-O1-Image-DevOpen-weight | 40.44 | 24.58 | 63.06 | 58.69 | 76.70 |
| 19 | GPT Image 1 [High]API-only | 37.91 | 22.91 | 60.01 | 52.20 | 70.85 |
| 20 | Hunyuan-Image-3.0Open-weight | 29.93 | 20.43 | 39.32 | 51.83 | 65.55 |
| 21 | FLUX.2 [Klein] 9BOpen-weight | 22.94 | 14.60 | 32.02 | 36.86 | 54.54 |
| 22 | FLUX.2 [Klein] 4BOpen-weight | 19.58 | 10.86 | 29.66 | 31.98 | 51.37 |
| 23 | FLUX.1 [Dev]Open-weight | 18.17 | 0.93 | 49.19 | 17.52 | 39.68 |
| 24 | SD3.5 LargeOpen-weight | 7.48 | 0.35 | 18.53 | 9.04 | 25.23 |
Composite weights: 60% fidelity, 30% clarity, 5% spatial, and 5% scene quality. Overall results equally average EN/ZH prompt-macro means. A score of 100 is the rubric ceiling, not a measured character-correctness percentage. Low / High denote API quality settings.
PUT YOUR MODEL TO THE TEST
The benchmark materials, evaluation code, and reported results are available now.
05 / CITE THE WORK
@misc{vtrbench2026,
  title={VTR-Bench: A Systematic Benchmark for Evaluating Visual Text Rendering in Video Generation},
  author={Yu Huang and Jungang Li and Zhiyuan Wang and Yonghua Hei and Song Dai and Jiayu Yang and Deyuan Liu and Xiang Zheng and Xiaoshuang Shi and Hao Cheng and Kaidi Xu},
  year={2026},
  eprint={2610.01499},
  archivePrefix={arXiv},
  primaryClass={cs.CV},
  url={https://arxiv.org/abs/2610.01499}
}

@misc{ultratextbench2026,
  title={UltraText Bench: A Comprehensive Bilingual Benchmark for Evaluating Visual Text Rendering in Image Generation},
  author={Deyuan Liu and Yihao Hu and Jingxuan Zhang and Xingying Li and Jun Xie and Jiacheng Liu and Jungang Li and Yu Huang and Xuanyi Liu and Yue Ding and Zecheng Wang and Lei Zhao and Mingda Wang and Zhenglin Cheng and Peng Sun and Tao Lin},
  year={2026},
  eprint={2610.09823},
  archivePrefix={arXiv},
  primaryClass={cs.CV},
  url={https://arxiv.org/abs/2610.09823}
}